Showing posts with label Procedural Cities. Show all posts

Wednesday, March 11, 2015

Population Explosion

I described in an earlier post my algorithm for placing the capital city in each of my countries, expanding on that I wanted to gather some more information about the make up of each country so I can make more informed descisions about further feature creation and placement.

One key metric is the population for the country as knowing how many people live in each country is key in deciding not just how many settlements to place but also how big they should be.  Until this is known much of the rest of the planetary infrastructure cannot be generated as so much of it is dependent upon the needs of these conurbations and their residents.
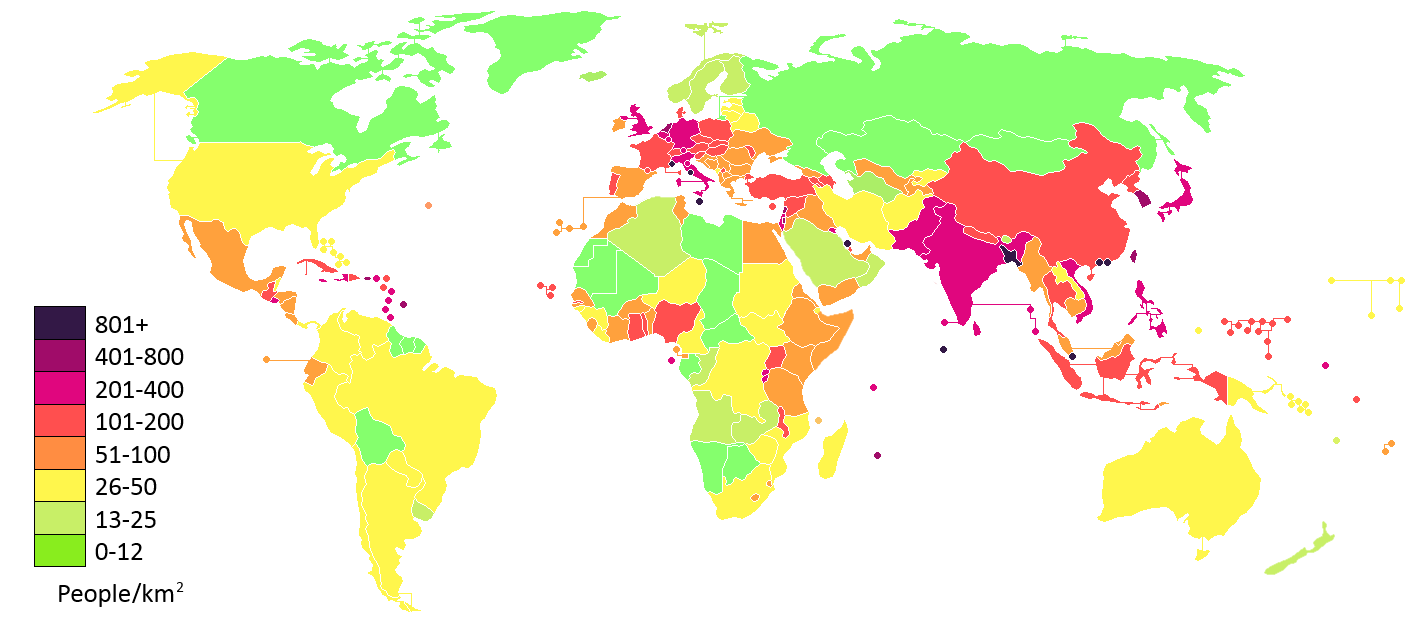
World population density by country in 2012.
(Image from Wikipedia)
A completely naive solution would be to simply choose a random number for each country but this would lead to future decisions that are likely to be completely inappropriate for both the constitution of the country's terrain and it's geographical location.  A step up from completely random would be to weight the random number by the country's area so the population was at least proportional to the size of the country but again this ignores key factors such as the terrain within the country - a mountainous or desert country for example is likely to have a lower population density than lush lowlands.

To try to account for the constitution of the country's physical terrain rather than just use the area I instead create a number of sample points within the country's border and test each of these against the terrain net.  As mentioned in a previous post, intersecting against the triangulated terrain net produces points with weights for up to three types of terrain depending on the terrains present at each corner of the triangle hit.  By summing the weights for each terrain type found on each sample point's intersection I end up with a total weight for each type of terrain giving me a picture of the terrain make across the entire country.  I can tell for example that a country is 35% desert, 45% mountains and 20% ocean.

This is of course just an estimate due to the nature of sampling but the quality of the estimate can easily be controlled by varying the distance between sample points at the expense of increased processing time.  Given a set number of samples however the quality of the estimate can be maximised by ensuring the points chosen are as evenly distributed across the country as possible.

The number of samples chosen for the country is calculated by dividing it's area by a fixed global area-per-sample value to ensure the sampling is as even across the planet's surface as possible - currently I'm using one sample per 2000 square kilometres.  Once the number is known the area of each triangle in the country's triangulation is used to see how many sample points should be placed within that triangle.  Any remainder area left over after that many samples worth of area has been subtracted is propagated to the area of the next triangle - this also applies if the triangle is too small to have even a single sample point allocated to it to make sure it's area is still accounted for.

If a triangle is big enough to have sample points allocated within it those points are randomly positioned using barycentric co-ordinates in a similar manner to how the capital cities were placed.  There is nothing in this strategy to prevent samples from adjacent triangles from falling close to each other but in general I am happy that it produces an acceptably even distribution with a quality/performance trade-off  that can easily be controlled by varying the area-per-sample value.

So given the proportion of each type of terrain making up a country how do I turn that into a population value?  I assign a number of people per square kilometre to each type of global terrain, multiply that by the area of the country then by the weight for that type of terrain to get the number of people living in that type of terrain in the country then finally sum these values for each terrain type to get the total number of people in the entire country.

I've produced these people-per-Km2 values largely by using the real world figures for population density found on Wikipedia as a basis.  Using figures a year or two old, the Earth has an approximate average population density of just 14 people per square kilometre when you count the total surface area of the planet but this rises to around 50 people per square kilometre when you count just the land masses.  

As shown on the infographic above however the huge variety factors influencing real world population density lead to some areas of the planet being very sparsely populated with only a couple of people per square kilometre while other areas have 1000+.  There isn't enough information present in my little simulation to reflect this diversity yet however so I'm currently working with a far more restricted diversity based around the real world mean.  The values I am currently using are:

Figures for how many "people" to create per square kilometre for each terrain type 
So given the fairly random distribution of terrain on my planet as it now stands what sort of results drop out of this?  Currently the terrain looks like this:

The visual planetary terrain composition, currently the ocean terrain type has a slightly higher weighting so there is more water surface area than any other single terrain type  
while making 100 countries produces the figures shown here

Terrain composition for a number of the countries along with their resultant population densities by total area and by landmass area
As can be seen basing the terrain population densities on real world values has generated a planetary population not too different to our own but as my planet is currently 24% water rather than the 70% or so found on Earth the actual densities are probably on the low side.  The global terrain composition is currently made up like this:

Proportion of the planet covered by each terrain type and resultant contribution to the planet's population

What is interesting is that the sampling strategy ensures that the population count properly reflects the proportion of the planet that is land mass - you can see countries such as Sralmyras which are 32% water have a lower population density by area of just 13 while Kazilia which is 7% water has a density of 17 people per Km2.

With a population count my plan is to now use that in conjunction with the terrain composition profile to derive a settlement structure for each country so I know how many villages, towns and cities to create.  Watch this space.

Saturday, February 7, 2015

Capital Cities

Following on from Country Generation, I thought I would take a look at placing some capital cities in my newly established countries as a precursor to more general settlement placement encompassing everything from hamlets and villages up to towns and other major cities.

As a quick recap, here is my planet with the country boundaries highlighted:


So the challenge here is to pick an essentially random  location within the country boundaries that is suitable for it's capital city.  As I already have a triangulation of the country to be used when deciding within which country a point on the planet's surface lies, I can use this to place the city.  Rather than picking random points on the planet in the hope of eventually finding one that lies within the country of interest however it makes more sense to pick points within the triangulation to start with.

The simplest way therefore would be to just pick a random triangle from the country's triangulation then pick a random point within it.  The first is trivial while the second can also be easily accomplished using barycentric co-ordinates to convert three random numbers in the range [0, 1] into a point within the triangle.

While this works, I didn't want capital city placement to be completely random, for my purposes I didn't want a capital city that was too close to the country boundaries but with the naive approach described above there is nothing to stop a capital being right on the border.  This is purely a subjective restriction and I'm sure somewhere in the world there is a capital very close to a border but it just didn't feel right to me.

Unfortunately determining the distance between a point within a country and it's border isn't a trivial task, requiring the distance to each line segment making up the border to be calculated and the minimum taken.  Determining what is an acceptable distance is also not as easy as it might be due to the wildly varying shapes of the countries.  An acceptable distance for a generally circular country might be impossible to satisfy for a different country that was long and thin.

There isn't much that can be done to alleviate the first issue other than test as few candidate points as possible and possibly use some sort of spacial index to reduce the number of border segments being processed - while it's a bit brute force however it's not prohibitively expensive so improving it isn't top priority.

Without any particular knowledge of a country's shape however determining an acceptable distance from the border to place the capital city is a bit more of a challenge.  Rather than try to work out some sort of heuristic from the border vertices I chose instead to use a sampling approach.  For each country a number of random points are generated using the simple algorithm above and the distance from each to the country's border calculated.  The point that is furthest from the border is chosen as the position of the capital city.


The number of points to test is a little trial and error - sample too few and you might not pick a point that's far enough away from the border to be acceptable while sample too many and you will inevitably end up with a point pretty much in the middle of every country which is too uniform and also unacceptable.

I ended up taking 25 sample points for each country which I think gives a decent spread of capital positions while still not generating any too close to the borders.

I am hoping the system can be extended to start placing secondary and tertiary settlements by adding other factors to the heuristic such as distance from already placed settlements (scaled by the relative sizes of each settlement) along with some physical factors such as the candidate site's proximity to rivers or bodies of water to encourage settlements in coastal areas and the general flatness of the terrain to make lowlands and valley floors more appealing than steep mountain sides.

For reference I thought it would be worth including an illustration of the triangulation generated from the country boundaries, as you can see the simple ear-clipping algorithm used tends to produce long thin triangles.  These don't affect the functionality of the system but at some point in the future I might be adding these triangles to some sort of spacial organiser to improve query performance in which case a triangulation that was a bit more evenly distributed across the surface might be better, but it will do for now.


Then of course there is generation of the actual cities themselves complete with road network and buildings, so there is as ever plenty to do!

Saturday, August 13, 2011

Building Placement Revisited

Although the building lot generation system I described in my earlier post did produce results, the quality of those results was far from ideal. Despite the time spent on it and the various techniques tried the lots it produced were neither very well distributed, controllable in formation nor very practically shaped. Rather than soldier on into procedural architecture generation with such ill suited foundations I decided to have one more attempt at cracking the problem, and I'm very glad I did.

Looking at it after a break of a few weeks not working on the project gave me a valuable fresh perspective and I realised that maybe the whole chart subdivision plan was flawed, maybe there was a better way. Rather than abandon charts altogether though I came up with a new way to use them - rather than splitting them up to try and make lots I thought it might be interesting to start with tiny "seed" lots placed in locations and with orientations I already knew to be sensible then apply some sort of iterative growth algorithm to let them fight it out in a sort of survival of the fittest manner.

The best starting position for this free-for-all seemed to be placing a seed lot half way along any chart edge longer than some minimum threshold. This not only ensured the lots would follow the roads exactly but also made it easy to determine the building front side. Each seed lot is a small square only a couple of metres in size, their initial placements in my test city can be seen here:

Seed points for lot generation
With these seed positions set the system then repeatedly iterates over each in turn attempting to grow them a small amount in each of the three directions not adjacent to the road. By growing each only slightly each time the lots all expand pretty evenly to fill the available space. Growth in a particular direction only stops when that edge of the lot hits another lot, an edge of the chart that contains it or if it has grown too far beyond the length of the chart edge that created it. Lots also stop growing in depth if it would cause them to be too much deeper than they are wide as it's rare to find many buildings significantly deeper than they are wide - the actual aspect ratio limitation can of course be tweaked.

Should a lot run out of space before it reaches the minimum size threshold required to place a building on it the lot is flagged as invalid and other lots allowed to grow into it's space if required. Once all lots have grown as much as possible the process is complete.

After a dozen iteration the above seed lot layout produces this completed result:

After 12 iterations no more lot growth is possible
It's immediately obvious that this new system produces a far more ordered and sensibly laid out set of building lots. They are all nice and rectangular, are oriented neatly along the roads while also using up most of the available space.

The image below illustrates where the invalid lots that didn't survive the cut were located:

Lots in red are too small for buildings and are discarded
Although all were rejected because they weren't large enough to put buildings on, you can see a couple have had their space partially used by other valid lots to maximise their own area.

One final check that is also performed is that building lots larger than a certain size are subdivided along their width into a number of sub-lots that meet the size criteria.  This maximum size is a function of the distance from the population centre so building lots nearer the centre of the city are allowed to be larger than those in the suburbs.  In the next image lots in blue are the result of subdivision in this way:

Lots in blue are the result of subdivision of larger lots
I'm not sure whether to keep this step or not, I think it depends on the variety of building that the architecture system will be able to produce - if believable large suburban buildings can be generated (shopping malls or sports centres perhaps, possibly large mansion type houses) then it would make sense to keep some large plots for their placement.  For now though I am keeping things aimed at houses in the 'burbs.

Placing my simple building place-holder object on these new lots and giving them heights based upon their distance from the population centre gives what I think is a fairly decent looking impression of a city for such a graphically simple representation:


Adding some road geometry with a number of lanes based upon the generation number of the road in the road network generation system and some basic pavements gives some other pleasing results:


Overall I'm quite happy with the new system and am definitely much happier about moving on to look at procedural architecture with this better foundation.  It shows if nothing else that if your instincts are telling you that a system is not up to the job, it's often best to listen to them!

A Note on Texture Filtering

This is just a short note to highlight the visual impact that mip map generation and texture filtering methods can have on a final rendered result. It's not rocket science and will be common knowledge to many, but I felt this was a nice clear example of how significant the effects can be and worth sharing.

I've recently been playing around with procedural city and road generation which has of course led to rendering of road surfaces for which I am using a trivially simple programmer art texture:

Source Road Lines Texture
Even though I knew that find detail on textures viewed at extreme angles are always troublesome, feeding this through the normal mip map generation code with the existing trilinear texture filtering however produced a surprisingly disappointing result:

Uniform Weight Mip Maps, Trilinear Filtering
As you can see, the white lines in the road vanish very quickly with distance as their light coloured texels are swamped by the dark road surface around them during mip map down sampling - not at all realistic and bad enough for me to take a second look. The first thing was to look at the mip map generation code to see if it could be persuaded to keep more of the detail that I cared about. Current each mip map level was being generated using a naive 2x2 box filter with uniform weights:

lower_mip_texel = (higher_mip_texel1+higher_mip_texel2+higher_mip_texel3+higher_mip_texel4)/4;

very easy, very fast but also very bad at keeping detail. There are many better filters out there with varying quality/performance tradeoffs but I thought it worth trying a quick and simple change to weight the pixels by their approximate luminosity, calculated by simply averaging each source texel's red, green and blue channels clamped to a chosen range:

higher_mip_texel_weight = Clamp((higher_mip_texel_red+higher_mip_texel_green+higher_mip_texel_blue)/3, 50, 255)
lower_mip_texel = (
    (higher_mip_texel1*higher_mip_texel_weight1)+
    (higher_mip_texel2*higher_mip_texel_weight2)+
    (higher_mip_texel3*higher_mip_texel_weight3)+
    (higher_mip_texel4*higher_mip_texel_weight4)/
        (higher_mip_texel_weight1+higher_mip_texel_weight2+
         higher_mip_texel_weight3+higher_mip_texel_weight4);

This then favours brighter texels which will be more visible in the final render. Using this code to generate the mip maps instead of the uniformly weighted filter produced immediately better results:

Luminosity Biased Mip Maps, Trilinear Filtering
While the white lines are now visible far more into the distance they become disproportionately fat as the lower mip level texels cover more and more screen space. There's not much that can be done about this as however we filter the texture when making the mip maps we are either going to end up with no white lines or bit fat ones.

The next step then is to stop using trilinear filtering at runtime and instead switch to anisotropic filtering where the filter kernel shape effectively changes with the aspect of the textured surface on screen so the GPU can for example filter a wider area of the texture in the 'u' axis than it does in the 'v' and has more information for choosing the mip level to read each filter sample from. Returning to the original uniformly weighted mip maps where the lines disappeared so early but switching to anisotropic filtering produces noticible better results than either attempt so far:

Uniform Weight Mip Maps, Anisotropic Filtering
and finally for good measure using the weighted mip maps with anisotropic filtering:

Luminosity Biased Mip Maps, Anisotropic Filtering
Not as dramatic effect as when switching to weighted mips with trilinear filtering but still an improvement and the best result of all.

So why not use anisotropic filtering all the time? well it comes down to compatibility and performance, not all legacy GPUs can support it although most modern cards can and even on cards that do there is a performance cost as the GPU is having to do significantly more work - the effects speak for themselves though and going forward I expect it will become the default setting for most games to avoid over-blurry textures as objects move away from the near plane.